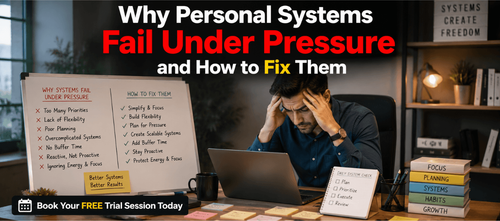
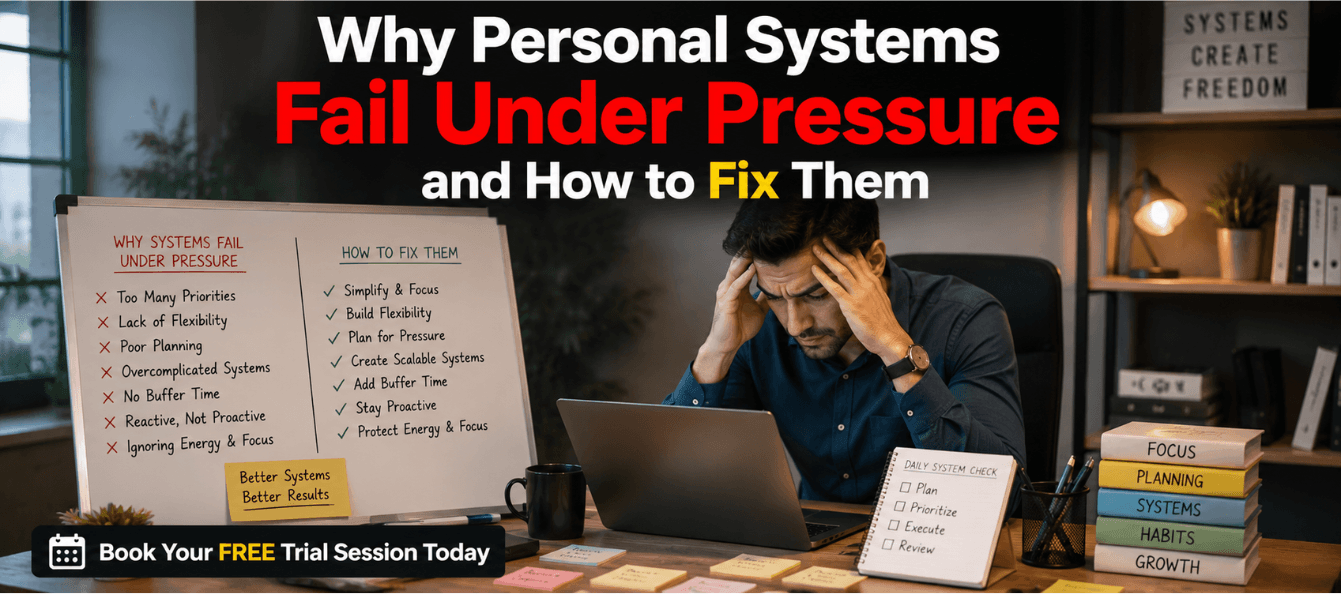
Why Personal Systems Fail Under Pressure and How to Fix Them
Diagnosing Why Your Systems Collapse Under Pressure and Build More Resilient Workflows
Most professionals believe their systems are working well—until pressure arrives. A workflow feels efficient during calm periods, routines seem manageable when workloads are stable, and productivity systems appear reliable under normal conditions. But the moment deadlines shift, priorities change, or unexpected demands appear, everything starts breaking down.
Tasks pile up, communication becomes chaotic, important details get missed, and professionals suddenly find themselves operating in survival mode instead of intentional execution.
What many people call “bad luck” is actually a systems problem. The truth is that most professionals build workflows optimized for ideal conditions instead of pressure conditions. They create systems that function well when everything is predictable but collapse the moment complexity, overload, or uncertainty enters the picture.
This guidebook introduces a practical self-assessment toolkit designed to help professionals identify the hidden fault lines inside their workflows, routines, communication systems, and decision-making processes before those weaknesses create major breakdowns.
Instead of constantly reacting to problems, professionals can learn how to diagnose vulnerabilities, redesign fragile systems, and build pressure-resistant workflows that remain functional even during demanding situations.
Download these resources and apply them alongside your daily work for improved clarity, productivity, and professional growth. You can also book a free trial to gain expert guidance and enhance your communication, problem-solving, and decision-making skills. The materials are designed in a clear, structured format to help professionals learn efficiently and implement insights with confidence.
Who Is This Blog For?
- Working professionals managing complex workloads and deadlines
- Managers leading teams under pressure and uncertainty
- Consultants and freelancers juggling multiple projects simultaneously
- Professionals struggling with overwhelm, reactivity, or workflow breakdowns
- Team leaders seeking stronger operational resilience
- Employees looking to improve productivity systems and decision-making
- Career-driven professionals aiming to reduce stress and improve consistency
Why Does System Collapse Happen So Frequently Today?
Modern professional environments create constant pressure.
Teams are expected to:
- Deliver faster results
- Handle multiple priorities simultaneously
- Adapt quickly to change
- Communicate continuously
- Operate with minimal recovery time
As workloads become more dynamic, many professionals unknowingly build fragile systems that depend on perfect conditions to function properly.
The guidebook explains that system collapse is rarely sudden.
Instead, it follows a predictable sequence:
- Overload
- Friction
- Avoidance
- Breakdown
- Reactive recovery mode
Professionals often ignore the early warning signs because systems appear functional on the surface.
However, beneath the surface:
- Workflows may rely too heavily on one person
- Processes may lack documentation
- Prioritization systems may fail under overload
- Communication channels may become chaotic during pressure spikes
- Teams may have no redundancy or backup structure
The result is a fragile system that works only when stress remains low.
Core Concept or Framework Explained
The guidebook introduces a diagnostic framework focused on identifying how and where systems fail under pressure.
The Anatomy of Collapse
The framework explains that collapse is not one event. It is a cascade.
Most system failures move through several predictable stages.
Signal Stage
Early warning signs appear but are often ignored.
Examples include:
- Increasing confusion
- Delayed responses
- Rising stress levels
- Small quality mistakes
Strain Stage
The system begins operating beyond healthy capacity.
Signs include:
- Faster decisions with less information
- Constant urgency
- Skipped quality checks
- Reduced planning time
Fracture Stage
Critical components start breaking.
Examples include:
- Communication breakdowns
- Missed deadlines
- Dependency failures
- Escalating confusion
Cascade Stage
One failure triggers additional failures throughout the system.
At this stage:
- Teams become reactive
- Priorities become unclear
- Recovery becomes difficult
- Stress compounds rapidly
The guidebook emphasizes that identifying your typical failure stage is one of the most valuable diagnostic insights you can develop.
How Does This Blog and Guidebook Help You?
This toolkit helps professionals move from reactive problem-solving to proactive system design.
The guidebook provides:
- A framework for diagnosing workflow vulnerabilities
- Pressure mapping exercises to identify stress sources
- Self-assessment tools for evaluating system resilience
- Practical methods for reducing fragility and overload
- Strategies for improving communication, prioritization, and recovery systems
- Structured reflection exercises for long-term improvement
The result is:
- Better decision-making under pressure
- Reduced operational chaos
- Improved workflow resilience
- Faster recovery after disruptions
- Greater professional clarity and consistency
Step-by-Step Breakdown
Step 1: Understand the Real Nature of System Collapse
The guidebook begins by reframing collapse itself.
Most professionals incorrectly assume:
- Collapse happens suddenly
- Collapse means incompetence
- Collapse is caused purely by workload
- Recovery requires simply working harder
The framework challenges these assumptions.
Instead, it explains that collapse usually results from poor system design.
Examples include:
- Work distributed unevenly
- No backup systems or redundancy
- Lack of documented workflows
- Overdependence on specific individuals
- No planning buffers
Understanding this changes how professionals approach problem-solving.
Instead of blaming themselves, they begin diagnosing system architecture.
Step 2: Identify Early Warning Signals
One of the strongest concepts in the guidebook is learning to recognize strain signals before collapse occurs.
Common warning signs include:
- Decisions being made faster but with less clarity
- Communication shortcuts replacing proper documentation
- Rising confusion around priorities
- Skipping quality-control steps
- Constant urgency with no recovery time
- Increasing dependency on memory instead of systems
These symptoms often appear weeks before major breakdowns happen.
The guidebook encourages professionals to treat these signals as diagnostic data rather than temporary inconvenience.
Step 3: Conduct a Pressure Audit
The Pressure Audit helps professionals map where pressure enters their systems.
The framework identifies four major pressure sources.
Time Compression
Examples include:
- Expanding project scope
- Compressed deadlines
- Excessive meetings reducing execution time
People Dependencies
Systems fail when they depend too heavily on one person being constantly available.
Examples include:
- Knowledge trapped in one employee’s head
- Approval bottlenecks
- Specialized responsibilities with no backup
Context Switching
Moving constantly between projects, clients, tools, or responsibilities reduces cognitive performance significantly.
This creates:
- Lower decision quality
- Increased errors
- Mental fatigue
- Reduced focus
Ambiguity Spikes
Unexpected changes in goals, expectations, or priorities destabilize systems quickly.
The guidebook encourages professionals to identify which pressure sources consistently trigger breakdowns in their workflows.
Step 4: Evaluate Your System Resilience Honestly
The self-assessment section is one of the most practical parts of the guidebook.
Professionals rate themselves across multiple resilience dimensions.
Examples include:
- Workflow documentation quality
- Ability to prioritize competing urgencies
- Backup systems during absence
- Recovery speed after disruptions
- Presence of planning buffers
- Communication clarity under pressure
- Decision-making quality during overload
The framework highlights especially dangerous combinations such as:
- Poor communication systems
- Hidden workflow dependencies
- Lack of redundancy
These create systems that are both fragile and opaque simultaneously.
Step 5: Identify Single Points of Failure
The guidebook explains that many systems collapse because too much responsibility is concentrated in one place.
Common examples include:
- One person handling all approvals
- One communication channel carrying all information
- One workflow tool supporting the entire system
- One leader making every decision
When these points fail, everything slows or collapses.
The framework recommends:
- Creating process visibility
- Cross-training team members
- Documenting key procedures
- Building redundancy intentionally
Pressure-resistant systems distribute critical responsibilities instead of centralizing them excessively.
Step 6: Build Buffer Capacity Into Your Systems
One of the most overlooked concepts in professional systems design is buffer capacity.
Many professionals operate with:
- Fully packed calendars
- No recovery time
- No contingency space
- No schedule flexibility
This means even small disruptions trigger cascading problems.
The guidebook encourages professionals to intentionally create:
- Calendar buffers
- Energy buffers
- Decision-making buffers
- Communication buffers
- Project contingency time
These buffers absorb pressure spikes before they destabilize the system.
Step 7: Create Recovery Systems Instead of Reactive Firefighting
Most professionals focus only on preventing breakdowns.
The guidebook emphasizes something equally important:
Recovery speed.
Pressure-resistant systems recover quickly after disruptions because recovery is designed intentionally.
Examples include:
- Clear escalation protocols
- Backup communication systems
- Prioritized recovery checklists
- Pre-decided responses for common pressure scenarios
Instead of improvising during crisis moments, professionals operate with structured recovery processes.
Real-World Application: Diagnosing a Team Workflow Breakdown
The guidebook describes a common scenario where a project team initially appears productive but collapses under deadline pressure.
Symptoms included:
- Endless status meetings
- Missed handoffs
- Conflicting priorities
- Rising confusion
- Increased overtime
The diagnosis revealed several hidden vulnerabilities:
- One manager controlled all approvals
- No documentation existed for key processes
- Team members lacked backup coverage
- Priorities changed constantly without communication updates
- No planning buffers existed
Instead of simply increasing effort, the team redesigned its systems by:
- Distributing responsibilities
- Improving documentation
- Adding workflow redundancy
- Creating structured communication protocols
- Building planning buffers
The result was improved resilience and significantly faster recovery during future pressure spikes.
Common Mistakes or Pitfalls to Avoid
The guidebook highlights several patterns that quietly weaken systems over time.
Ignoring Early Signals
Professionals often dismiss warning signs until collapse becomes unavoidable.
Better approach:
- Treat strain indicators seriously early
Confusing Busyness With Effectiveness
High activity levels can hide poor system design.
Better approach:
- Evaluate workflow quality, not just workload volume
Relying on Heroics
Many teams depend on individuals “saving the day” repeatedly.
Better approach:
- Build systems that function without constant emergency effort
Skipping Documentation
Undocumented systems become fragile under pressure.
Better approach:
- Create workflows others can follow independently
Operating Without Buffers
Fully optimized schedules collapse quickly when disruption occurs.
Better approach:
- Intentionally create margin and recovery space
Only Fixing Problems After Failure
Reactive improvement creates recurring instability.
Better approach:
- Conduct regular system reviews during calm periods
How Should You Use This Guidebook Effectively?
The guidebook is designed as a practical diagnostic and redesign toolkit.
Recommended workflow:
- Read the entire framework once without judgment
- Complete the self-assessment honestly
- Identify your most common collapse stage
- Map your primary pressure sources
- Identify single points of failure
- Introduce one resilience improvement at a time
- Conduct monthly or quarterly reviews
Suggested time investment:
- 60–90 minutes for the initial diagnostic process
- 20–30 minutes weekly for system reviews
- 60 minutes monthly for resilience reassessment
The guidebook emphasizes gradual improvement rather than attempting complete system redesign overnight.
Pressure-resistant systems are built incrementally through awareness, redesign, and consistent refinement.
Key Takeaways
- System collapse is usually a design problem, not bad luck
- Most failures happen gradually through predictable stages
- Early warning signals often appear long before major breakdowns
- Pressure audits help identify the true sources of stress and instability
- Single points of failure create fragile workflows
- Buffer capacity improves resilience dramatically
- Documentation and redundancy reduce operational risk
- Recovery systems matter as much as prevention systems
- Regular reviews during calm periods strengthen long-term resilience
- Sustainable performance depends on system design, not constant heroics
Your Next Step: Accelerate Your Career with PlanetSpark
Creating an impact-driven resume is not just about landing your next job—it’s about owning your professional story and presenting it with clarity, confidence, and credibility. When your resume clearly communicates value, results, and impact, opportunities follow naturally.
At PlanetSpark, we are committed to empowering working professionals with practical, outcome-focused resources that drive real career growth. From resume building and workplace communication to leadership presence and professional writing, our programs are designed to help you succeed in today’s fast-evolving job market.
Visit https://www.planetspark.in/resources to explore:
- Career and resume-building guides
- Workplace communication and professional writing resources
- Skill-development tools curated for working professionals
Want a deeper, hands-on experience?
You can also book a free trial session to learn more about PlanetSpark’s Working Professional Courses, designed to accelerate your career through personalised coaching, real-world practice, and expert guidance.
Your career deserves more than generic advice.
It deserves clarity, confidence, and measurable impact.
Start building that advantage today—with PlanetSpark.
Personalized Communication Roadmaps
Record a video to get a AI generated personalized communication reports